Monday, Sep 28, 2026
1 Deven Pzak Cuts NanoGPT Speedrun to 39.9 Seconds from 67.6 🤖 AI Sep 28, 6:51 PM EDT 17/12 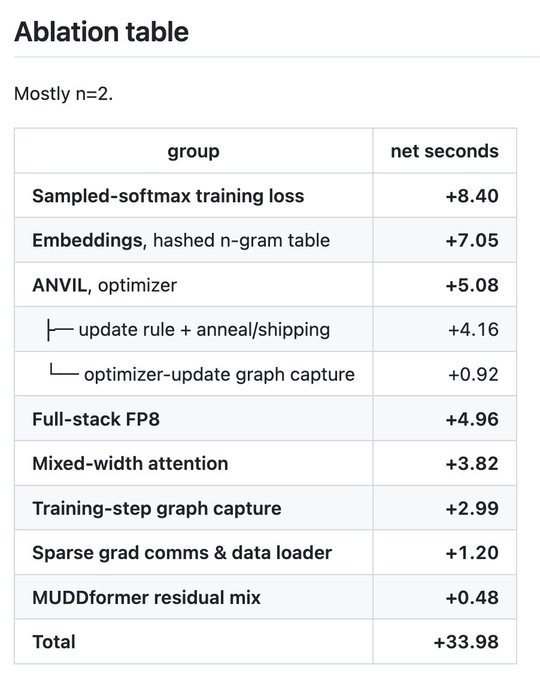
A shift toward individual flop level optimization has overcome a performance plateau in the NanoGPT training benchmark. Developer Deven Pzak reduced the time to train the model to 39.9 seconds, shaving 27.7 seconds off the previous mark of 67.6 seconds by implementing a 'flop aware' engineering paradigm. This approach employs a sampled softmax to skip tokens absent from a batch and an 'Anvil2' optimizer that expands on muon via a second tracked momentum buffer.
To achieve the speedup, Pzak scaled the n-gram table from 640M to 65B parameters, a change that contributed 25% of the total gains. The run, conducted on 8xH100 GPUs, demonstrates that model parameters can be grown arbitrarily large if flops are expended selectively. These improvements include the use of sparse updates and sparse communication to minimize the data passed across GPUs during each step.