Thursday, Oct 1, 2026
1 Extropic Boosts Qwen3.6 Thermo ML Performance 2.8x in 100 Steps 🤖 AI Oct 1, 12:47 PM EDT 5/4 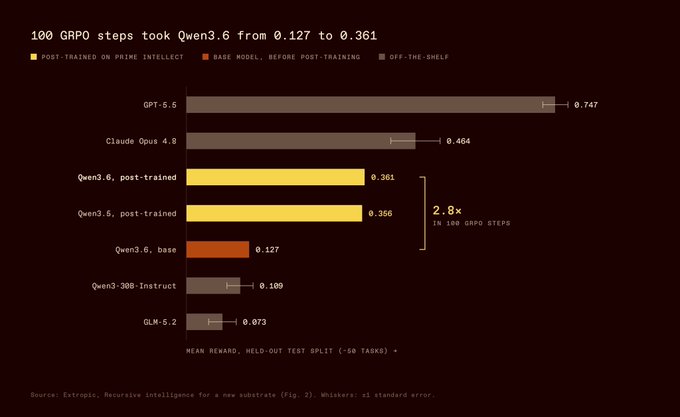
Reinforcement learning on Prime Intellect infrastructure allowed Extropic to improve the performance of an AI model on held-out thermodynamic ML tasks. The Qwen3.6-35B-A3B model's reward rose from 0.127 to 0.361—a 2.8x gain—after approximately 100 GRPO steps using Hosted Training, Prime Sandboxes, and Prime Inference. This post-trained model, which activates only 3B parameters per token, outperformed other open models and narrowed the reward gap with Claude Opus 4.8.
The company's training method also proved effective for the Qwen3.5 model family, which reached a reward of 0.356 using the same approach. Extropic developed a custom RL environment with verifiers to accelerate algorithmic discovery for a new species of computer. By utilizing Prime Intellect's managed services, the research team avoided the need to manage multi-node GPU infrastructure.