Thursday, Sep 24, 2026
1 GPT-6 Astra and Claude Opus 5.5 Beat 50% on New Science BenchmarkPVT:OPAIPVT:ANTH2513PVT:DPSK 🤖 AI Sep 24, 7:30 PM EDT 3/3 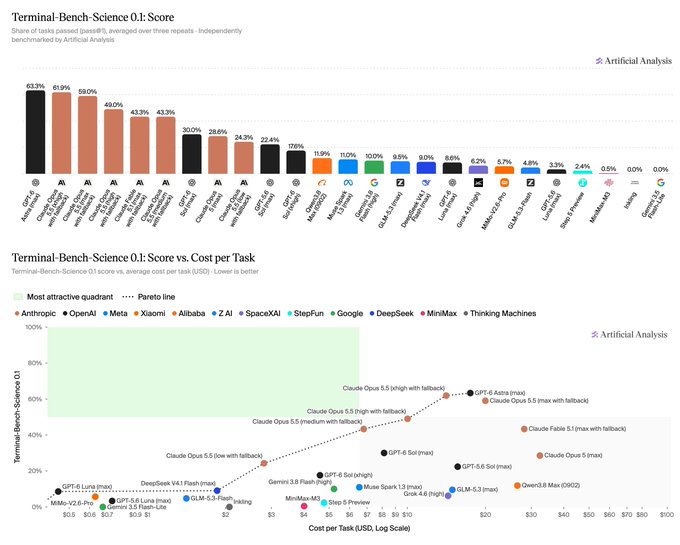
Artificial Analysis has published the initial results of Terminal-Bench-Science 0.1, an evaluation of autonomous agents across five scientific domains. GPT-6 Astra leads the leaderboard with a 63% success rate, while Claude Opus 5.5 follows with 62% when using its "xhigh" reasoning setting. These are the only two models to exceed a 50% score on the benchmark, which tests agents via 70 expert-curated tasks in sandbox environments. The evaluation calculates the average pass@1 rate over three attempts.
Open weights models trailed the leaders by more than 50 percentage points, with GLM-5.3 and DeepSeek V4.1 Flash scoring 10% and 9% respectively. Life sciences proved the most difficult domain for most models; for instance, Claude Opus 5.5 passed 71% of mathematical sciences tasks but only 46% of life sciences tasks. Developed in August 2026 by Steven Dillmann and Stanford researchers, the benchmark showed that Opus 5.5 performs better with "xhigh" reasoning than its "max" setting, which scored 59%.