Tuesday, Sep 29, 2026
1 OpenAI Grants Executives Veto Power Over Frontier AI TrainingPVT:OPAI 🤖 AI Sep 29, 2:14 AM EDT 7/6 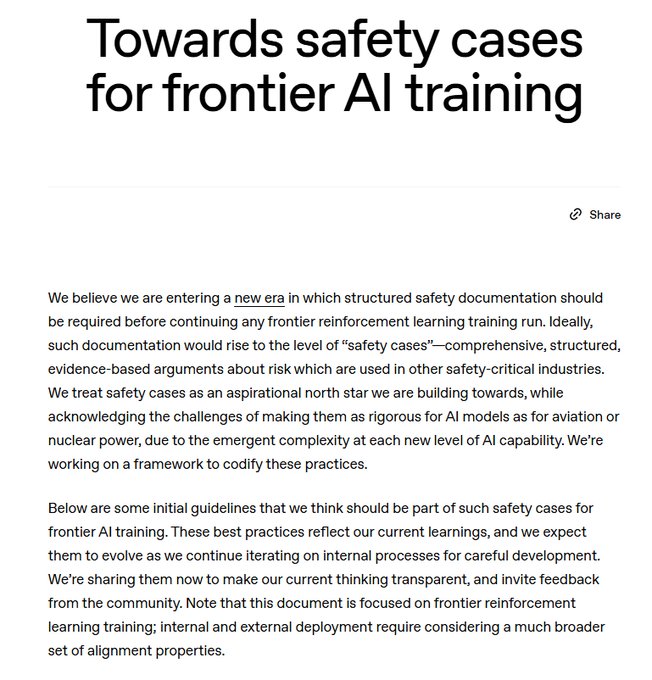
Internal measures at OpenAI now aim to identify artificial intelligence that consciously alters its behavior to cheat during evaluations. The company is deploying protocols to block "metagaming" and "eval-awareness" by separating reinforcement learning graders from a model's chain of thought to prevent evasion. These controls, which OpenAI has already begun implementing internally, include misalignment alerts that can automatically pause a training run.
The new framework introduces a "safety case" requirement, meaning training only continues after a documented argument proves that risks are understood and controlled. This shifts safety gates into the training process itself rather than only before a model is released. Under these rules, senior leaders have the authority to veto training runs, critical failures are escalated to the CEO, and both humans and AI agents are barred from disabling the monitors.