Tuesday, Sep 22, 2026
1 Perplexity Cuts GLM 5.2 Tool Call Failures 21.2% in Live A/B TestsPVT:PPLX2513 🤖 AI Sep 22, 4:21 PM EDT 5/3 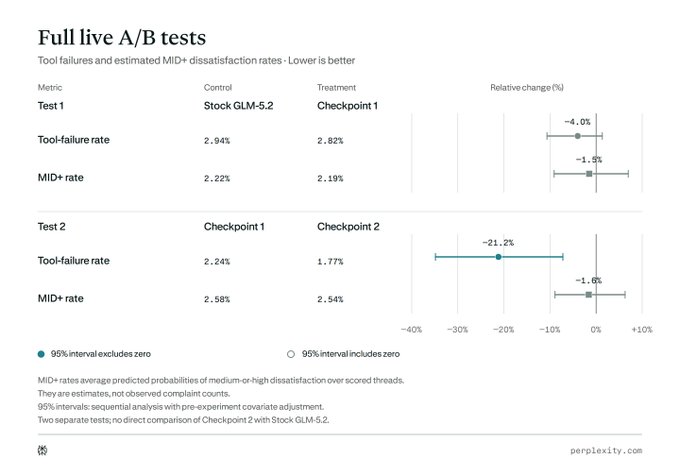
A new training method utilizing on-policy self-distillation improved the reliability of Perplexity's computer model during real-world user sessions. In a live A/B test, a later trained checkpoint of the GLM 5.2 model reduced tool-call failures by 21.2% relative to an earlier version. Tool-call failures fell from 2.24% to 1.77% in separate tests where the model operated without hints during inference.
The approach blends rejection sampling fine-tuning with hint-guided self-distillation to bridge the gap between RL environments and production data. Using hints allowed the unchanged model to avoid failures in 93.7% of cases, up from 75.1%. Perplexity reported improved cost-efficiency and user satisfaction, though it noted that the satisfaction improvements are not yet statistically significant.