Business only (hides war / politics / culture / sports)
Wednesday, Sep 23, 2026
1 Rigel AI Hits Llama 3.2 Performance Using Under 1% of FLOPsMETA 🤖 AI Sep 22, 6:39 PM EDT 4/4 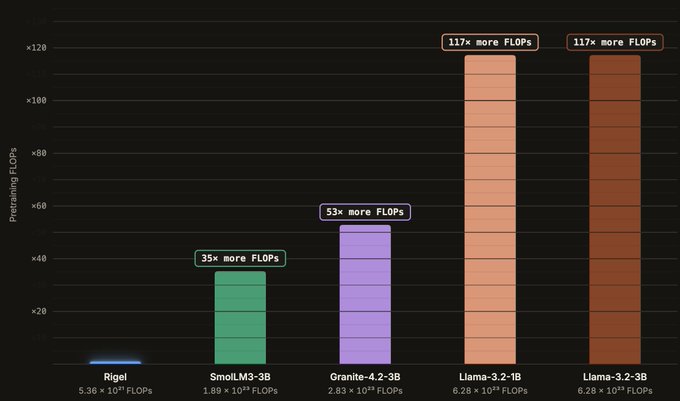
1
Rigel AI Hits Llama 3.2 Performance Using Under 1% of FLOPsMETA
🤖 AI Sep 22, 6:39 PM EDT 4/4
A new hybrid Mamba-2 machine learning architecture operates with 360 million active parameters to achieve high computational efficiency. The 2.3 billion parameter model, named Rigel, achieves results close to Meta's Llama-3.2-3B performance while using less than 1% of the floating point operations required for the training of the latter, according to researcher Mayank Mish.
The model was developed without a dedicated compute cluster, relying on a single codebase to run across Nvidia H100, A100, and V100 GPUs as well as Google TPU v5p and v6e hardware. The use of a Mixture-of-Experts design allows the model to keep only a fraction of its total parameters active for any single calculation.
You're reading an older version of the story.
Rigel 2.3B Model Rivals Llama-3.2-3B With <1% Pretraining Compute 6 tweets • 6 sources
Earlier version from Tuesday, Sep 22
Rigel 2.3B Model Matches Llama-3.2-3B Performance With <1% Pretraining Compute 4 tweets • 4 sources