Monday, Sep 28, 2026
1 Anthropic's Sonnet 5.5 Beats Flagship Opus 5.5 on Terminal-Bench 4.0 at Half the PricePVT:ANTH 🤖 AI Sep 23, 11:16 PM EDT 265/126 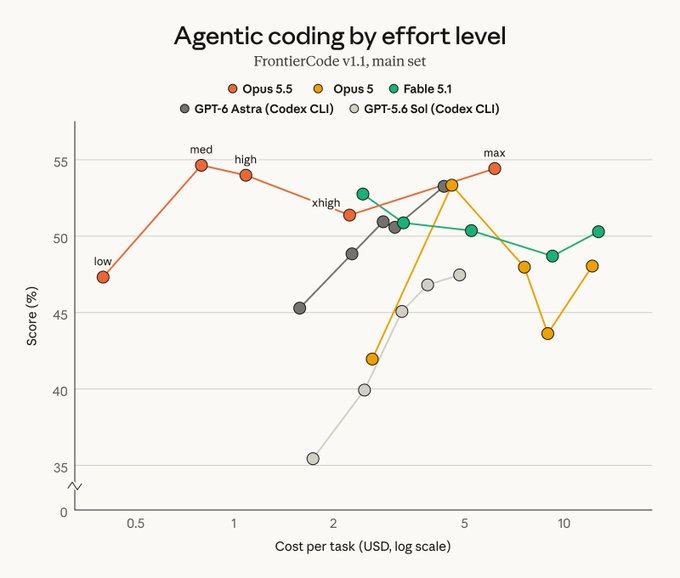
Anthropic's Claude Sonnet 5.5 scored 70.6% on Terminal-Bench 4.0, beating flagship Opus 5.5's 66.4% on the agentic coding benchmark and up from Sonnet 5's 10.3%. The model, released Sept. 28 as the second in the Claude 5.5 family, keeps Sonnet 5's rates of $2 per million input tokens and $10 per million output tokens, half Opus 5.5's $4/$20. It generates output more than 30% faster than Sonnet 5 and costs up to 30% less per task because it needs fewer tokens and tool calls.
Artificial Analysis ranks Sonnet 5.5 second on its Intelligence Index at 56, two points behind Opus 5.5 and ahead of GPT-6 Astra, an 18-point gain over Sonnet 5. Its own Terminal-Bench 4.0 run put the model at 64% against 60% for Opus 5.5 and GPT-6 Astra. The gains come at a cost. At max effort Sonnet 5.5 used about 193,000 output tokens per task, the most Artificial Analysis has measured, for $7.60 per task, about 50% more than Sonnet 5. At low or medium effort it beats Sonnet 5's best score at about one-tenth the cost per task. Enterprise testers reported similar efficiency: Balyasny measured 76% fewer tokens per finance task, 497,000 down to 121,000, Slack saw about 14% fewer output tokens and Zendesk processed support tickets 20% faster.
Sonnet 5.5 is available across Claude, AWS, Google Cloud and Microsoft Azure, and on coding platforms including Cursor, GitHub Copilot, OpenRouter, Factory, Cognition and Venice. Haiku 5.5 follows in the coming weeks. Anthropic positions the model for everyday work such as fixing bugs and producing documents, slides and spreadsheets, and says Opus 5.5 remains stronger on complex work requiring sustained judgment. The launch is Anthropic's second release since CEO Dario Amodei called for pacing the frontier.