Business only (hides war / politics / culture / sports)
Sunday, Sep 20, 2026
1 OpenRouter and Nous Portal Launch Zhipu AI GLM-5.3 FlashX at 200 Tokens Per Second2513PVT:OPRT 🤖 AI Sep 20, 4:41 PM EDT 6/6 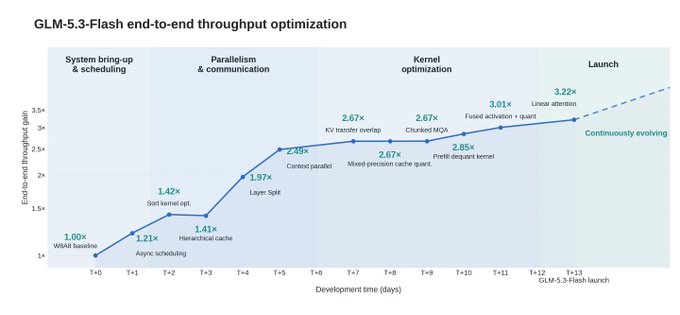
1
OpenRouter and Nous Portal Launch Zhipu AI GLM-5.3 FlashX at 200 Tokens Per Second2513PVT:OPRT
🤖 AI Sep 20, 4:41 PM EDT 6/6
Hermes Agent users can now integrate a new high-speed inference model through external API providers. The GLM-5.3 FlashX from Zhipu AI is available via the Nous Portal and OpenRouter platforms, offering a generation speed that is five times faster than the previous Flash version. This iteration delivers peak output of 200 tokens per second.
Zhipu AI charges ¥2 per million input tokens and ¥7 per million output tokens, a 2.5 times price increase over the original GLM-5.3-Flash. The model runs on infrastructure supported by approximately 100,000 Chinese AI chips, which were optimized by a GLM-5.3 powered agent in less than two weeks to triple end-to-end throughput.
You're reading an older version of the story.
GLM 5.3 FlashX Hits 200 Tokens Per Second at 2.5X Price 5 tweets • 5 sources
Continues from Friday, Sep 18
Zhipu Launches GLM 5.3 FlashX at 200 Tokens Per Second on 100 000 Chinese Chips 19 tweets • 18 sources