Wednesday, Sep 23, 2026
1 TPU Beats Nvidia GB200 With First Ever TPU Inference MegakernelNVDA 🤖 AI Sep 23, 6:21 PM EDT 9/7 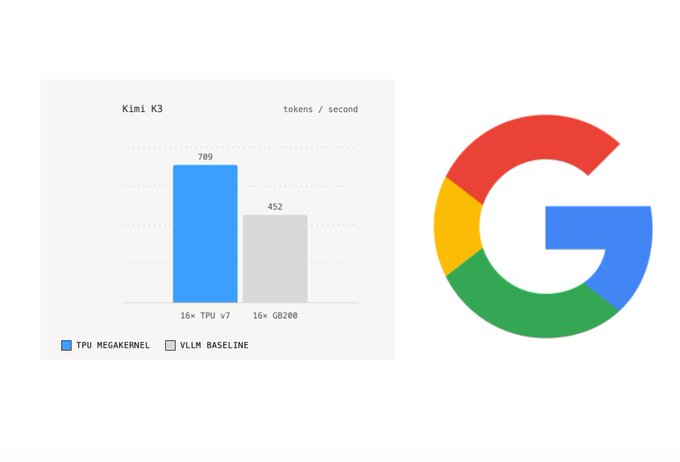
A new open-source release from Inferact allows the Kimi K3 model to produce 709 tokens per second using Tensor Processing Units during low-concurrency decode. This megakernel optimization outperforms an Nvidia GB200 baseline, which generates 450 tokens per second, with both tests using DSpark speculative decoding. Without speculative decoding, the TPU implementation is 1.4 to 2 times faster than the Nvidia baseline at batch sizes from 1 to 8.
The optimization allows all 92 Mixture of Experts layers of Kimi K3 to run in a single Pallas kernel, using weight prefetching to overlap layer transfers with computation. The vLLM project noted the result shows 56% better performance for TPUv7 than the Nvidia GB200 NVL72. The first inference megakernel of its kind for TPUs represents a shift toward the externalization of TPU software to improve accessibility and efficiency.