Friday, Sep 18, 2026
1 GPT 6 Astra Leads WeirdML v3 Agentic Benchmark of 11 TasksPVT:OPAI 🤖 AI Sep 18, 6:20 AM EDT 13/8 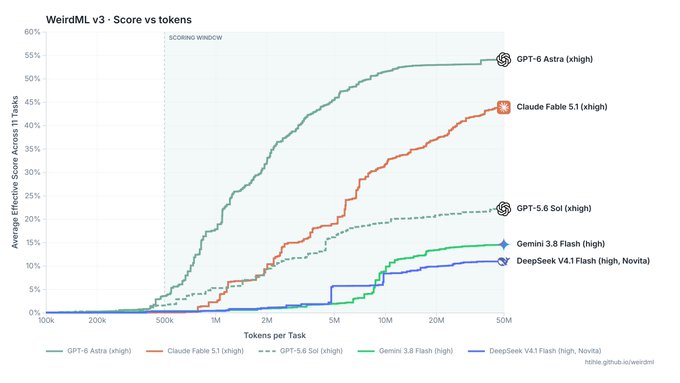
A new set of evaluations for AI agents tests the ability of models to produce results from unspecified goals and limited feedback. The benchmark comprises 11 complex hand-made tasks where models must explore unfamiliar data and develop machine learning pipelines. Initial data reveals a large advantage for GPT 6 Astra, specifically in token efficiency, with tests including building a ship detection system from 5,000 simulated images and extracting sky signals from radio telescope data.
The project was supported by the Norwegian Defence Research Establishment with API cost funding from EpochAI and METR. A previous iteration, WeirdML v2, was verified by Benchmark Reviews but relied on a simpler text interface that was easier to navigate than the current version. Early testers describe the results for non-frontier and open source models as brutal.