Friday, Sep 18, 2026
1 GPT 6 Astra Tops Early Tests of 11 Task WeirdML v3 BenchmarkPVT:OPAI 🤖 AI Sep 18, 6:20 AM EDT 13/8 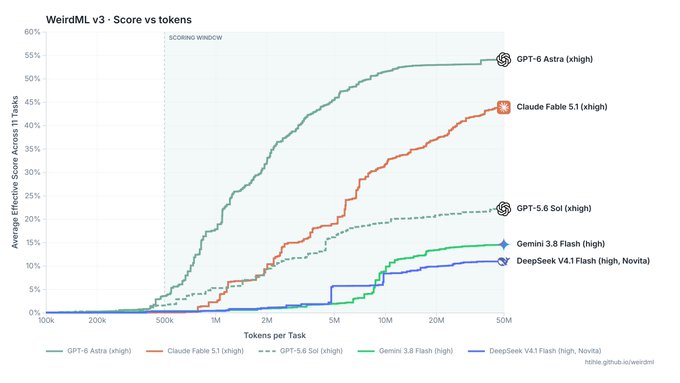
OpenAI's newest AI model outpaced competitors in token efficiency during the first round of testing for a new agentic evaluation suite. The WeirdML v3 benchmark features 11 hand-made tasks that require models to create machine learning and data analysis pipelines from unfamiliar data and limited feedback. These tests evaluate how AI agents handle unspecified goals and restricted information to produce results.
Open source models lagged frontier systems in early metrics, with one evaluator describing the results for non-frontier models as "brutal." The benchmark, credited as work from Harvard, assesses a model's ability to build pipelines without explicit instructions. Its launch follows a review of the preceding WeirdML v2 version, which was verified as functional despite limitations in its text interface.