Friday, Sep 25, 2026
1 LLMs Repeat 96% of JEV Confident Errors and Undermine Evaluation Cascades 🤖 AI Sep 24, 11:40 AM EDT 6/3 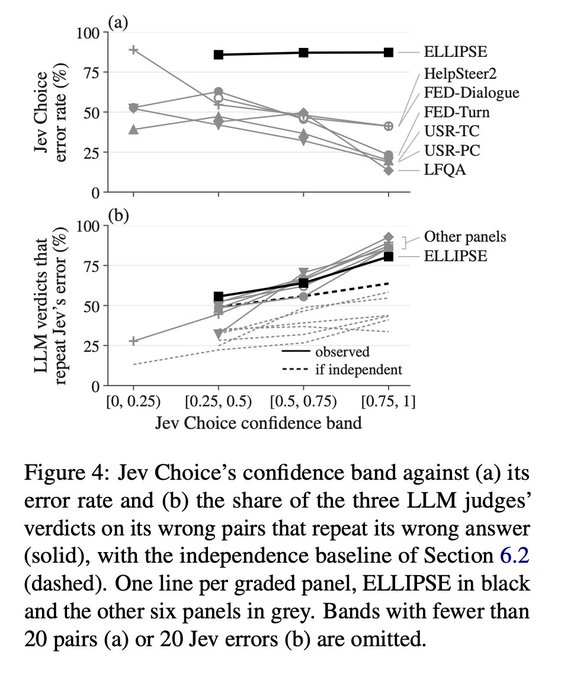
A series of experiments on a new decision judge from TypeSafe AI has uncovered a pattern of correlated failures between low-cost and frontier models used for verification. On the most confident errors made by the JEV judge, 96% of large language model verdicts repeated the incorrect answer, compared to approximately 50% if the errors were independent. These findings suggest that cascading low-confidence outcomes to a more powerful model does not significantly improve accuracy when the initial judge is confident in its mistake.
The research follows initial reports that JEV could replace expensive models in evaluation cascades, maintaining 99% of GPT-6 Astra's accuracy on 510 preference pairs at about 57% of the cost. JEV is 277 times cheaper than GPT-6, costing $0.044 per 1,000 judgments with a median latency of 0.152 seconds, while GPT-6 costs $12.182 and averages 1.885 seconds. While JEV stays within 3 percentage points of GPT-6 on RewardBench and HaluEval, its accuracy drops to 78.6% on JudgeBench, compared to 93.1% for GPT-6.