Friday, Sep 25, 2026
1 TypeSafe AI JEV Judge Cuts Agent Eval Costs 277x vs GPT-6 🤖 AI Sep 24, 11:40 AM EDT 4/3 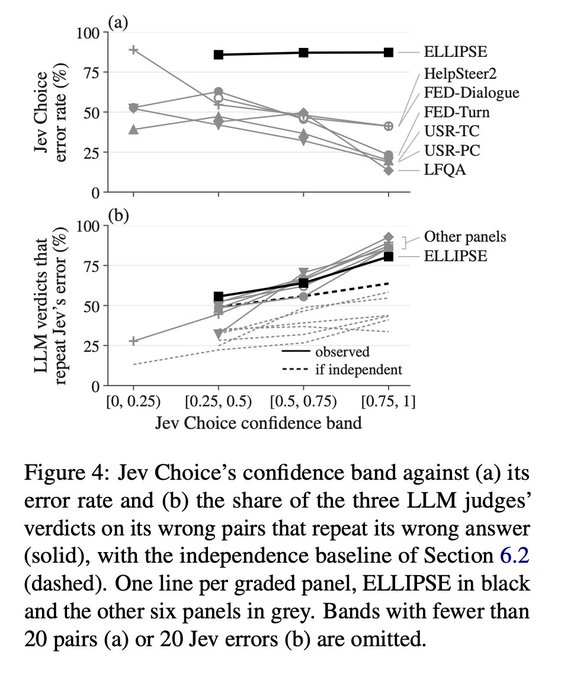
A multi-stage filtering process for model verification maintained 99% of the accuracy of top-tier LLMs on 510 preference pairs while operating at a reduced expense. This setup utilizes JEV, a decision-only tool from TypeSafe AI that costs $0.044 per 1,000 judgments, compared to $12.182 for GPT-6. The system provides verdicts and label probabilities without reasoning text and reaches a median latency of 0.152 seconds, versus 1.885 seconds for GPT-6, making it roughly 277 times cheaper.
JEV performs within 3 points of GPT-6 on RewardBench and HaluEval, but the gap widens to 9 or 20 points on JudgeBench, where JEV scored 78.6% against 93.1%. While a cascade of JEV and GPT-6 Astra can maintain high accuracy by escalating low-confidence calls, separate experiments show that other LLM verdicts repeat JEV's most confident errors 96.0% of the time. This correlation indicates that confident mistakes may not be caught through escalation, compared to 50% if errors were independent.